AI Engineer
Studio JaduBuilding multimodal text–image–video models for Studio Jadu's animation pipeline: tooling that extends what a small team can produce, with artists and storytellers directing the work at every step.
Rectified flow
The background is a flow matching field. Flow matching trains a velocity field to carry a simple distribution — here a Gaussian cloud of samples — onto a data distribution, which in this case is the photograph.
Rectified flow is the variant that couples each noise sample to its data sample along a straight line. The velocity is then constant, so the paths you see are exactly straight — and a model that learns them can be integrated in a handful of steps, rather than the many small ones a diffusion sampler's curved trajectories need.
Zürich, Switzerland
I work on multimodal models for text, image and video. My PhD: getting vision–language models to hold up in a domain as demanding as art — and working out how they get there.
 AI EngineerStudio Jadu
 PhD candidateUniversity of Bari Aldo Moro
Building multimodal text–image–video models for Studio Jadu's animation pipeline: tooling that extends what a small team can produce, with artists and storytellers directing the work at every step.

Vision–language models and multimodal AI at CILab, supervised by Prof. Giovanna Castellano and Prof. Gennaro Vessio, funded by Italy's NRRP Mission 4. Two threads run through it: getting these models to hold up in a domain as demanding as art, and working out how they arrive at what they say. Thesis submitted September 2026; defence expected December 2026.
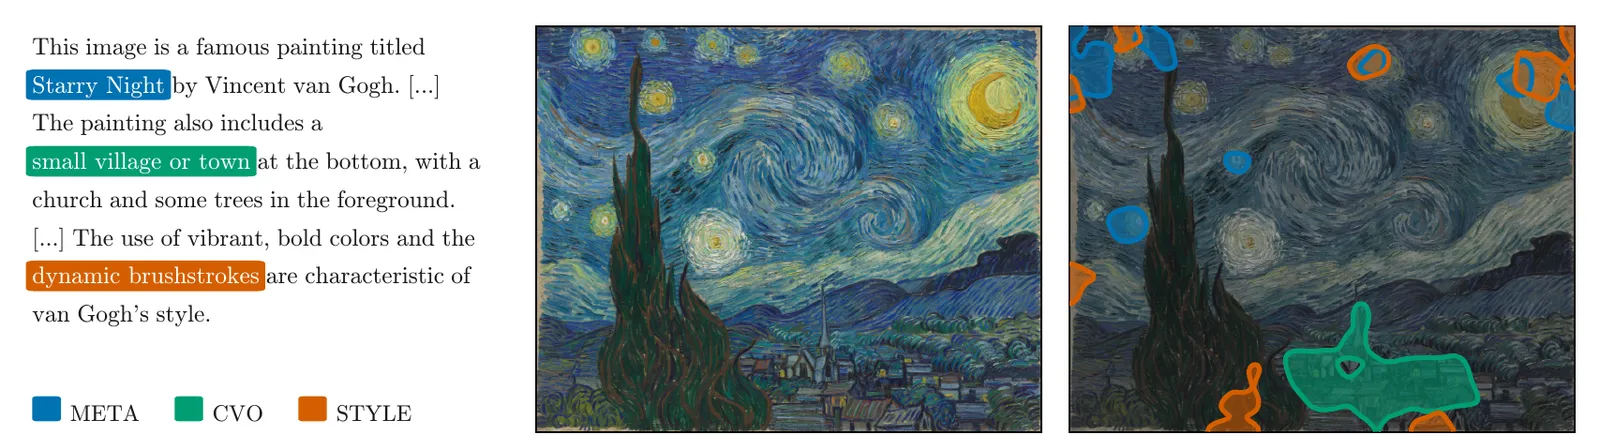
Best Paper Honorable Mention — IEEE CIS Italy Chapter, IJCNN 2025